Linear Algebra
A dataset can be stored as a matrix, with one row per example and one column per feature. Multiplying by a vector of weights produces a prediction for each row. We will review these calculations and the geometry behind them, including when a matrix transformation can be reversed.
Matrix Action
A vector \(\mathbf x\in\mathbb R^d\) is an ordered collection of \(d\) numbers. Bold symbols denote vectors: \(\mathbf x_i\) is vector \(i\), while \(x_j\) is coordinate \(j\) of a single vector \(\mathbf x\). When we index both examples and coordinates, \(x_{ij}=(\mathbf x_i)_j\) is coordinate \(j\) of example \(i\). We keep parenthesized superscripts for iteration steps, such as \(\mathbf w^{(t)}\). The inner product combines two vectors \(\mathbf u,\mathbf v\in\mathbb R^d\) into one number: \[ \langle\mathbf u,\mathbf v\rangle =\sum_{k=1}^d u_kv_k. \] An inner product can combine a feature vector with a weight vector to produce one prediction.
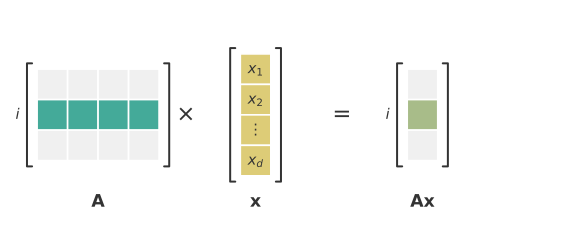
A matrix \(\mathbf A\in\mathbb R^{m\times d}\) maps an input \(\mathbf x\in\mathbb R^d\) to an output \(\mathbf A\mathbf x\in\mathbb R^m\). The \(i\)th output entry is the inner product of row \(i\) of \(\mathbf A\) with \(\mathbf x\): \[ [\mathbf A\mathbf x]_i =\sum_{k=1}^d A_{i,k}x_k. \] Each row therefore specifies how one output coordinate combines the input coordinates.
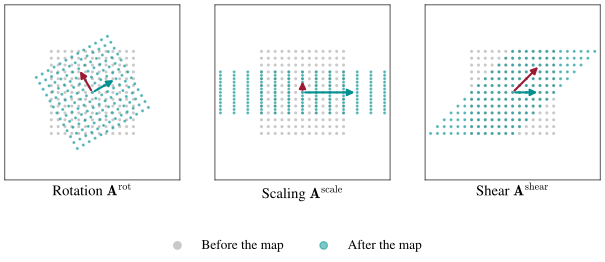
A matrix also describes a geometric transformation. Scaling changes coordinate magnitudes, shear offsets one coordinate by a multiple of another, and rotation changes direction while preserving length. In the plane, their matrices can be written as \[ \mathbf A^{\mathrm{scale}} =\begin{bmatrix}s_1&0\\0&s_2\end{bmatrix}, \qquad \mathbf A^{\mathrm{shear}} =\begin{bmatrix}1&h\\0&1\end{bmatrix}, \qquad \mathbf A^{\mathrm{rot}} =\begin{bmatrix}\cos\theta&-\sin\theta\\\sin\theta&\cos\theta\end{bmatrix}. \] Here \(s_1,s_2\) are scale factors, \(h\) is the shear amount, and \(\theta\) is the counterclockwise rotation angle.
Transpose
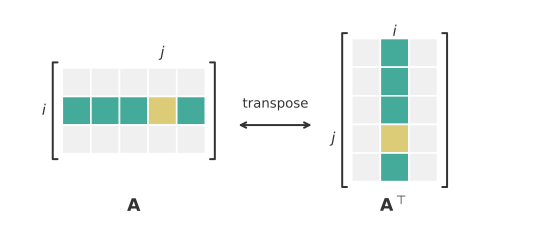
The transpose swaps the rows and columns of a matrix. For \(\mathbf A\in\mathbb R^{m\times d}\), its transpose \(\mathbf A^\top\in\mathbb R^{d\times m}\) satisfies \[ [\mathbf A^\top]_{i,j}=[\mathbf A]_{j,i}. \] Row \(i\) of \(\mathbf A\) becomes column \(i\) of \(\mathbf A^\top\).
Matrix Multiplication
Suppose \(\mathbf A\in\mathbb R^{m\times d}\) and \(\mathbf B\in\mathbb R^{d\times p}\). The product \(\mathbf A\mathbf B\in\mathbb R^{m\times p}\) represents the composition that applies \(\mathbf B\) first and \(\mathbf A\) second.
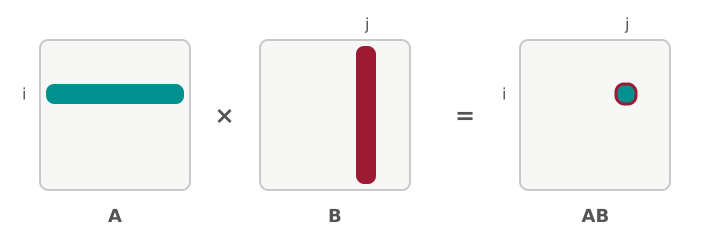
Inner-product form. Entry \((i,j)\) of the product is the inner product of row \(i\) of \(\mathbf A\) with column \(j\) of \(\mathbf B\): \[ [\mathbf A\mathbf B]_{i,j} =\left\langle[\mathbf A]_{i,:},[\mathbf B]_{:,j}\right\rangle =\sum_{k=1}^d A_{i,k}B_{k,j}. \] The shared dimension \(d\) is the length of both vectors in this inner product.
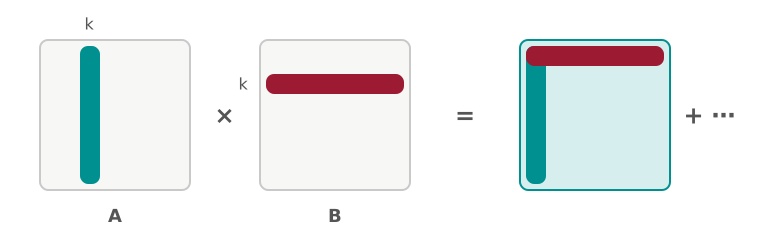
We can instead group the scalar products by the shared coordinate \(k\). For each \(k\), one column of \(\mathbf A\) multiplies one row of \(\mathbf B\) to produce an \(m\times p\) matrix.
Claim: Matrix multiplication has the equivalent outer-product form \[ \mathbf A\mathbf B =\sum_{k=1}^d [\mathbf A]_{:,k}[\mathbf B]_{k,:}. \]
Proof
For a fixed \(k\), column \(k\) of \(\mathbf A\) and row \(k\) of \(\mathbf B\) form the outer product \[ [\mathbf A]_{:,k}[\mathbf B]_{k,:} = \begin{bmatrix} A_{1,k}\\ \vdots\\ A_{m,k} \end{bmatrix} \begin{bmatrix} B_{k,1}&\cdots&B_{k,p} \end{bmatrix}. \] Its entry \((i,j)\) is \(A_{i,k}B_{k,j}\). Summing the outer products over \(k\) therefore makes entry \((i,j)\) equal to \[ \begin{aligned} \left[ \sum_{k=1}^d [\mathbf A]_{:,k}[\mathbf B]_{k,:} \right]_{i,j} &=\sum_{k=1}^d \left[[\mathbf A]_{:,k}[\mathbf B]_{k,:}\right]_{i,j}\\ &=\sum_{k=1}^d A_{i,k}B_{k,j}\\ &=[\mathbf A\mathbf B]_{i,j}. \end{aligned} \] The last line is the inner-product definition of matrix multiplication. The two matrices agree in every entry \((i,j)\), so they are equal.
The figure expands matrix multiplication into a sum of column-row outer products. Each nonzero outer product has rank one, and their sum has the same dimensions as \(\mathbf A\mathbf B\). The highlighted \((i,j)\) entry follows the same sum through every line.
Order matters because \(\mathbf A\mathbf B\) and \(\mathbf B\mathbf A\) apply the transformations in opposite orders. They may have different dimensions, and even when both products exist, they are generally unequal.
Time Complexity
The cost of a matrix product follows directly from its inner-product form. An inner product of two length-\(d\) vectors uses \(d\) multiplications and \(d-1\) additions, so it takes \[ O(d) \] time.
For \(\mathbf A\in\mathbb R^{m\times d}\) and \(\mathbf x\in\mathbb R^d\), the product \(\mathbf A\mathbf x\) has \(m\) entries. Computing one length-\(d\) inner product for each entry takes \[ m\,O(d)=O(md) \] time.
For \(\mathbf A\in\mathbb R^{m\times d}\) and \(\mathbf B\in\mathbb R^{d\times p}\), the product \(\mathbf A\mathbf B\) has \(mp\) entries. Computing one length-\(d\) inner product for each entry takes \[ mp\,O(d)=O(mdp) \] time. The output dimensions count how many inner products we need, while the shared inner dimension determines the cost of each one.
Inverses
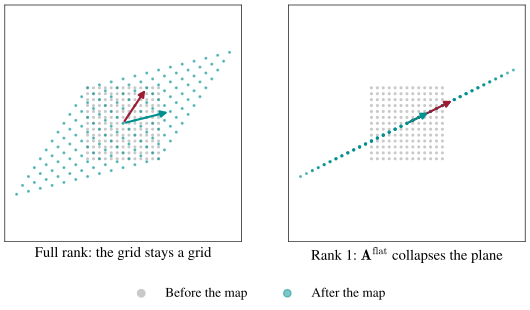
Some square matrices preserve the distinction between every pair of inputs, while others collapse distinct inputs together. A square matrix \(\mathbf A\in\mathbb R^{d\times d}\) is full rank when its \(d\) columns are linearly independent. A nonzero rank-one matrix has only one independent column direction, so all of its outputs lie along one line.
The identity matrix \(\mathbf I\) leaves every vector unchanged. An inverse of \(\mathbf A\) is a matrix \(\mathbf A^{-1}\) that undoes its action from either side: \[ \mathbf A^{-1}\mathbf A =\mathbf A\mathbf A^{-1} =\mathbf I. \]
Claim: A square matrix \(\mathbf A\in\mathbb R^{d\times d}\) is invertible exactly when it has full rank: \[ \mathbf A^{-1}\text{ exists} \quad\Longleftrightarrow\quad \operatorname{rank}(\mathbf A)=d. \]
Proof
First suppose \(\mathbf A^{-1}\) exists. If \(\mathbf A\mathbf x=\mathbf 0\), then multiplying by the inverse gives \[ \mathbf x=\mathbf A^{-1}\mathbf A\mathbf x=\mathbf A^{-1}\mathbf0=\mathbf0. \] No nonzero combination of the columns can equal zero, so the \(d\) columns are linearly independent and \(\mathbf A\) has full rank.
Now suppose \(\mathbf A\) has full rank. Its \(d\) independent columns form a basis of \(\mathbb R^d\). For \(j=1,\ldots,d\), let \(\mathbf e_j\) be the standard basis vector with entry \(j\) equal to one and all other entries zero. Each \(\mathbf e_j\) has a unique input \(\mathbf b_j\in\mathbb R^d\) satisfying \(\mathbf A\mathbf b_j=\mathbf e_j\). Collect these inputs into \(\mathbf B=[\mathbf b_1\ \cdots\ \mathbf b_d]\in\mathbb R^{d\times d}\). Multiplying column by column gives \[ \mathbf A\mathbf B=[\mathbf e_1\ \cdots\ \mathbf e_d]=\mathbf I. \] For any \(\mathbf x\in\mathbb R^d\), this identity gives \(\mathbf A(\mathbf B\mathbf A\mathbf x)=\mathbf A\mathbf x\). Because the columns of \(\mathbf A\) are independent, an output has only one input, so \(\mathbf B\mathbf A\mathbf x=\mathbf x\). Thus \(\mathbf B\mathbf A=\mathbf I\) as well, and \(\mathbf B\) is the inverse of \(\mathbf A\).
A matrix preserves enough information to recover every input exactly when it has full rank. Without full rank, distinct inputs collapse to the same output and no inverse can separate them again.