Logistic Regression
So far, our supervised learning models have predicted real-valued labels. In classification, the label is a category: an email is spam or not spam, or an image shows one of ten digits. We will adapt the same recipe by turning linear scores into class probabilities, choosing a loss through likelihood, and fitting the weights with gradient descent.
Binary Classification
Start with two classes, encoded as \(0\) and \(1\). For the email filter, let \(1\) mean spam and \(0\) mean not spam. The random variable \(Y\in\{0,1\}\) denotes the class. A lowercase \(y\) denotes a label we have actually observed. Our input is a feature vector \(\mathbf x\in\mathbb R^d\), where \(d\) is the number of features and \(x_j\) is feature \(j\). Features might record aspects of a message’s words or sender.
As in linear regression, combine the features using a weight vector \(\mathbf w\in\mathbb R^d\). To include an intercept, we can make one feature always equal to \(1\). Its weight then supplies the constant term. This lets us use the same notation throughout: \[ z=\mathbf w^\top\mathbf x =\sum_{j=1}^d w_jx_j. \] We call \(z\) the score. Each \(w_j\) controls how feature \(j\) contributes.
Logistic regression turns the score into a probability using the sigmoid function: \[ p=\sigma(z)=\frac{1}{1+e^{-z}}, \qquad \Pr_{\mathbf w}(Y=1\mid\mathbf x)=p, \qquad \Pr_{\mathbf w}(Y=0\mid\mathbf x)=1-p. \] The subscript on \(\Pr_{\mathbf w}\) emphasizes that these are the model’s probabilities at the current parameters. They are estimates of the actual conditional class probabilities, which we generally do not know. The scalar \(p\) always refers to class \(1\).
A positive score gives \(p>1/2\), a negative score gives \(p<1/2\), and a zero score gives \(p=1/2\). Predicting the more probable class means choosing class \(1\) for \(p>1/2\) and class \(0\) for \(p<1/2\). The classes tie where \[ \mathbf w^\top\mathbf x=0. \] For \(\mathbf w\ne\mathbf0\), this is a line with two features, a plane with three, and a hyperplane in general. In the feature space, \(\mathbf w\) is perpendicular to this hyperplane. A constant feature allows the boundary to shift relative to the original measurements. If \(\mathbf w=\mathbf0\), the model predicts \(p=1/2\) everywhere.
Sigmoid Function

The sigmoid changes smoothly across this linear decision boundary. Multiplying \(\mathbf w\) by a positive factor preserves the dividing hyperplane while making probabilities away from the boundary more extreme as the factor grows. The predicted class and confidence are therefore different aspects of the model.
The score also has a probability interpretation. The odds of class \(1\) are its probability divided by that of class \(0\). For the sigmoid, \[ \frac{p}{1-p}=e^z, \qquad \log\frac{p}{1-p}=z=\mathbf w^\top\mathbf x. \] Thus logistic regression assumes that the log odds are linear in the chosen features. Increasing a nonconstant feature \(x_j\) by one while holding the other features fixed adds \(w_j\) to the log odds and multiplies the odds by \(e^{w_j}\). This describes how the model’s prediction varies with the feature. A causal interpretation requires additional assumptions about the data-generating process.
Binary Cross-Entropy Loss
Now suppose we observe \(n\) training examples \((\mathbf x_i,y_i)\), for \(i=1,\ldots,n\). The subscript \(i\) indexes examples. For instance, \(x_{ij}=(\mathbf x_i)_j\) is feature \(j\) of example \(i\). At the current parameters, write \[ z_i=\mathbf w^\top\mathbf x_i, \qquad p_i=\sigma(z_i). \] These predictions depend on \(\mathbf w\). During fitting, the observed features and labels stay fixed while the parameters vary.
A binary outcome with class-\(1\) probability \(p_i\) has a Bernoulli distribution. The probability assigned to the observed label can be written in one expression: \[ \Pr_{\mathbf w}(Y=y_i\mid\mathbf x_i) =(p_i)^{y_i}(1-p_i)^{1-y_i}. \] The exponents select the correct class: when \(y_i=1\) this is \(p_i\), and when \(y_i=0\) it is \(1-p_i\). We want the model to assign high probability to the labels that actually occurred.
Assuming the labels are conditionally independent given their features, their joint likelihood is \[ L(\mathbf w) =\prod_{i=1}^n (p_i)^{y_i}(1-p_i)^{1-y_i}. \] As in the previous reading, maximizing this product is equivalent to minimizing its negative logarithm. Dividing by \(n\) makes the loss an average without changing its minimizers. Using natural logarithms, we obtain \[ \begin{aligned} \mathcal L(\mathbf w) &=-\frac1n\log L(\mathbf w)\\ &=-\frac1n\sum_{i=1}^n \log\left[(p_i)^{y_i}(1-p_i)^{1-y_i}\right]\\ &=-\frac1n\sum_{i=1}^n \left[y_i\log p_i+(1-y_i)\log(1-p_i)\right]. \end{aligned} \] This is binary cross-entropy. Just as the Gaussian observation model gave squared error, the Bernoulli observation model gives this loss through the same likelihood argument.
Cross-entropy penalizes the model for assigning low probability to the observed class. Assigning that class probability \(0.9\) incurs a small loss. Assigning it probability \(0.01\) incurs a much larger loss. This is why a confidently wrong prediction is costly.
The two plots below connect a classifier to its loss on a fixed set of labeled points. Here we use two features, without a constant feature, so the boundary passes through the origin. The left plot shows the decision boundary and its perpendicular weight vector. The right plot shows the cross-entropy loss at the same weights.
Decision Boundary and Loss
Multiclass Classification and Cross-Entropy Loss
Handwritten-digit recognition has ten mutually exclusive classes, one for each digit from \(0\) to \(9\). In the MNIST dataset, each image is a \(28\times28\) grid of pixel intensities. We flatten it by reading across the first row, then the second, and so on, giving a vector \(\mathbf x\in\mathbb R^{784}\). We scale the entries to \([0,1]\), where \(0\) is black and \(1\) is white. The highlighted pixels below become the matching entries of the vector. The displayed values use this \([0,1]\) scale.
Image to Vector
Row 13, columns 12–14 → entries 348–350. Each value is the pixel intensity ÷ 255.
Drag across the image to select three neighboring pixels. You can also focus the image and use the arrow keys.
We now need a probability vector \(\mathbf p\in\mathbb R^k\) for \(k\) classes, with \(p_j\) the probability assigned to class \(j\), indexed from \(1\) to \(k\). Its entries must be nonnegative and sum to one. For MNIST, \(k=10\), and class \(j\) corresponds to digit \(j-1\). Appending a constant feature to the 784 pixel intensities gives \(d=785\) features in the model used below.
Give each class its own weight vector \(\mathbf w_j\in\mathbb R^d\). Here \(j\) indexes classes. Place \(\mathbf w_j^\top\) in row \(j\) of \(\mathbf W\in\mathbb R^{k\times d}\). The vector of class scores is \[ \mathbf z=\mathbf W\mathbf x\in\mathbb R^k, \qquad z_j=\mathbf w_j^\top\mathbf x. \] These scores are also called logits. In the image example, each class has a separate set of pixel weights describing evidence for that class. The scores themselves need not be positive or sum to one.
Applying a sigmoid separately to every score would produce numbers between zero and one, but their sum would generally not be one. For mutually exclusive classes, softmax makes the scores compete through a shared denominator: \[ p_j=[\operatorname{softmax}(\mathbf z)]_j =\frac{e^{z_j}}{\sum_{l=1}^k e^{z_l}}, \qquad j=1,\ldots,k. \] Exponentiation makes every contribution positive, and dividing by their total makes the probabilities sum to one. The index \(l\) runs over every class in the denominator. \(j\) identifies the particular class whose probability we are computing. Increasing one score increases its share of the total and reduces the other classes’ shares.
The next figure reshapes the learned pixel weights for each digit into the original \(28\times28\) grid. The weight of the constant feature is omitted. Teal pixels contribute positively to that digit’s score, and indigo pixels contribute negatively. Several weight maps resemble the digit they recognize, but they also learn where ink helps distinguish it from other digits.
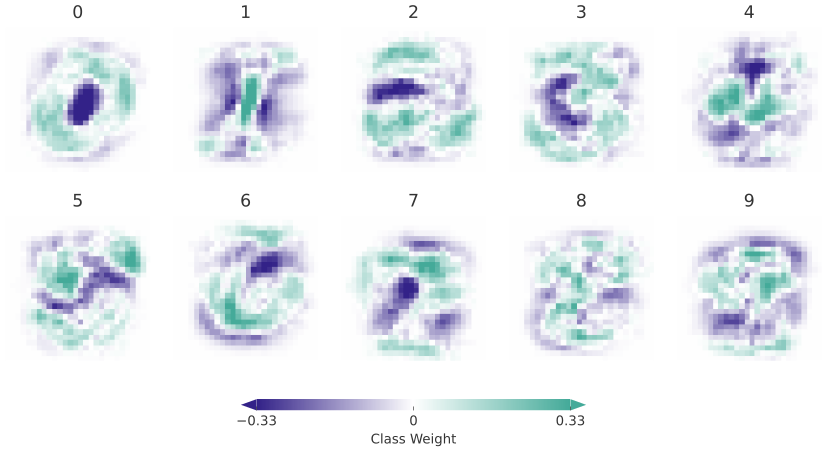
The weights come from the same softmax model trained in the demo, using 5,000 training images. For display, each pixel’s weights are centered across the ten classes. This subtracts the same quantity from every class score, leaving softmax probabilities unchanged because the common exponential factor cancels.
There is a direct analogue of the binary boundary picture. Exponentiation preserves ordering, and all classes share the same denominator, so the largest probability belongs to the largest score. Classes \(j\) and \(l\) tie when \[ z_j=z_l \quad\Longleftrightarrow\quad (\mathbf w_j-\mathbf w_l)^\top\mathbf x=0. \] For distinct class weight vectors, this is a hyperplane. Only the portions where the tied scores are also largest form decision boundaries. A tie between two losing classes does not change the prediction. Each winning region is where one score beats all the others.
To derive the multiclass loss, let \(c_i\in\{1,\ldots,k\}\) be the observed class of example \(i\). Encode it as a one-hot vector \(\mathbf y_i\in\{0,1\}^k\): its entry \(y_{ij}=(\mathbf y_i)_j\) is one when \(j=c_i\) and zero otherwise. Here bold \(\mathbf y_i\) is an entire label vector, unlike the scalar binary label used earlier. Let \(\mathbf p_i\) be the corresponding vector of predicted probabilities, with \(p_{ij}=(\mathbf p_i)_j\) for class \(j\). The probability of the observed class is \[ \Pr_{\mathbf W}(Y=c_i\mid\mathbf x_i) =p_{i,c_i}. \] Conditional independence again gives a product over examples, and taking the average negative log gives: \[ \begin{aligned} L(\mathbf W) &=\prod_{i=1}^n p_{i,c_i},\\ \mathcal L(\mathbf W) &=-\frac1n\log L(\mathbf W) =-\frac1n\sum_{i=1}^n\log p_{i,c_i}. \end{aligned} \] This is categorical cross-entropy: the same negative log-probability of the observed class, now with more possible labels. A confidently wrong prediction can therefore have a large loss even when most other examples are classified correctly. For a fixed input, if the predicted distribution matches the true class distribution, the expected cross-entropy is that distribution’s entropy: a measure of its uncertainty. We will return to this connection when studying language models.
Optimization
We have a model and a loss. We still need to choose the weights. For least squares, setting the gradient to zero produced linear equations in the parameters. Here the predicted probabilities depend on those parameters through sigmoid or softmax, so the corresponding equations are nonlinear and generally have no closed-form solution. We therefore use gradient descent, which requires the gradient of the training loss. Let \(\ell_i\) denote the cross-entropy loss of example \(i\), so our objective is \[ \mathcal L=\frac1n\sum_{i=1}^n\ell_i. \] The gradient of this average is the average of the individual gradients. We can therefore differentiate one example’s loss first, temporarily omitting its index and writing \(\ell\).
Claim: The derivative of softmax cross-entropy with respect to a class score is its probability residual: \[ \frac{\partial\ell}{\partial z_j}=p_j-y_j. \]
Why the Derivative Is a Residual
Let \(c\) be the correct class. Substituting softmax into the loss gives \[ \ell =-\log p_c =-z_c+\log\sum_{l=1}^k e^{z_l}. \] The derivative of \(z_c\) with respect to \(z_j\) is one when \(j=c\) and zero otherwise, exactly \(y_j\). Therefore, \[ \frac{\partial\ell}{\partial z_j} =-y_j+\frac{e^{z_j}}{\sum_{l=1}^k e^{z_l}} =p_j-y_j. \]
For binary logistic regression, the derivative with respect to its single score is likewise \(\partial\ell/\partial z=p-y\), where \(p\) is the probability of class \(1\) and \(y\in\{0,1\}\).
To apply this result to the weights, differentiate through the linear score. Since class \(j\) has score \(z_j=\mathbf w_j^\top\mathbf x\), the chain rule gives \[ \nabla_{\mathbf w_j}\ell =(p_j-y_j)\mathbf x. \] The key sign comes from gradient descent: we subtract the gradient. For a step using only this example, with learning rate \(\alpha>0\), the change in class \(j\)’s weights is \[ \Delta\mathbf w_j=-\alpha(p_j-y_j)\mathbf x. \] To see what this does to the score of the same example, take the dot product with \(\mathbf x\): \[ \Delta z_j=(\Delta\mathbf w_j)^\top\mathbf x =-\alpha(p_j-y_j)\|\mathbf x\|_2^2. \] For a nonzero feature vector, \(\alpha\|\mathbf x\|_2^2\) is positive, so the two cases are:
| Class | Probability residual | Effect on this example’s score |
|---|---|---|
| Correct class: \(y_j=1\) | \(p_j-1<0\) | Subtract a negative: score rises. |
| Every other class: \(y_j=0\) | \(p_j>0\) | Subtract a positive: score falls. |
Thus the update raises the probability of the observed class. The correction for the correct class scales with \(1-p_c\): assigning it probability \(0.1\) gives a factor of \(0.9\), while assigning it probability \(0.9\) gives a factor of \(0.1\). As \(p_c\) approaches one, all the other probabilities approach zero, so every class’s correction becomes small.
For the training set, average these gradients across examples, then subtract a small multiple of the average from the current weights. Recompute the probabilities and repeat. Because the weights are shared, different examples’ corrections can compete. Averaging combines their contributions. The demo implements this average with a single matrix multiplication.