Depth Enablers
A deeper network can build features through more stages of computation. To train its early layers, backpropagation must pass a gradient through every later layer. Repeated multiplication can make that gradient extremely small or large.
We will follow the products in backpropagation and examine how choices about weight scale and layer structure affect the gradients used to train early layers.
Motivation
Start with one number per layer so that we can isolate the effect of repeatedly multiplying derivatives. Write \(h^{(0)}=x\) for the input and let each of the \(L\) layers compute \[ z^{(l)}=w^{(l)}h^{(l-1)},\qquad h^{(l)}=g(z^{(l)}). \] Here \(w^{(l)}\) is a scalar weight and \(g\) is an activation function. The derivative through one layer is \(\partial h^{(l)}/\partial h^{(l-1)}=g'(z^{(l)})w^{(l)}\). For one example’s loss \(\ell\), the chain rule multiplies these derivatives: \[ \frac{\partial\ell}{\partial h^{(0)}} =\left(\prod_{l=1}^L g'(z^{(l)})w^{(l)}\right) \frac{\partial\ell}{\partial h^{(L)}}. \] If every local derivative has magnitude \(r\), the gradient’s magnitude is multiplied by \(r^L\). For that multiplier to stay close to one in a deep network, \(r\) must be very close to one.
Repeated factors below one make the early gradients vanish, leaving little signal for their weight updates. Repeated factors above one make them explode, so a small learning rate may be needed to keep those updates controlled. For vector-valued layers, each backward step multiplies by a matrix. Different directions can then shrink or grow by different amounts, so we need the matrix form of the chain rule from Neural Networks.
At layer \(l\), let \(n_{\mathrm{in}}\) and \(n_{\mathrm{out}}\) be the input and output widths. The weight matrix \(\mathbf W^{(l)}\in\mathbb R^{n_{\mathrm{out}}\times n_{\mathrm{in}}}\) computes the weighted sums, then \(g\) acts on each coordinate: \[ \mathbf z^{(l)}=\mathbf W^{(l)}\mathbf h^{(l-1)},\qquad \mathbf h^{(l)}=g(\mathbf z^{(l)}). \] Here \(\mathbf h^{(l-1)}\in\mathbb R^{n_{\mathrm{in}}}\) and \(\mathbf z^{(l)},\mathbf h^{(l)}\in\mathbb R^{n_{\mathrm{out}}}\). Each weighted sum uses all the inputs, while each activation uses just its own weighted sum.

To track how the layer changes gradients, collect its local derivatives in a Jacobian, with one row per output and one column per input. Its \((i,j)\) entry is \(g'(z_i^{(l)})W_{ij}^{(l)}\), so \[ \mathbf J^{(l)} =\frac{\partial\mathbf h^{(l)}}{\partial\mathbf h^{(l-1)}} =\operatorname{diag}\!\left(g'(\mathbf z^{(l)})\right)\mathbf W^{(l)}. \] The diagonal matrix scales each row of \(\mathbf W^{(l)}\) by that output’s activation derivative. The multivariate chain rule sends gradients backward by multiplying by the transpose. Across all \(L\) layers, \[ \nabla_{\mathbf h^{(0)}}\ell =\left[\prod_{l=1}^L (\mathbf W^{(l)})^\top \operatorname{diag}\!\left(g'(\mathbf z^{(l)})\right)\right] \nabla_{\mathbf h^{(L)}}\ell. \] The product is ordered with layer \(1\) on the left and layer \(L\) on the right. The rightmost matrix acts first, so the gradient travels backward through layer \(L\) first. For ReLU, we use derivative zero at its corner, as in Neural Networks.
This product is the matrix counterpart of \(r^L\). A layer’s Jacobian describes how it stretches small changes in different directions. We want these multiplications to keep gradients at a comparable scale as they pass through the network. There are three places to intervene:
- Initialization: choose the weight scale using \(n_{\mathrm{in}}\) and \(n_{\mathrm{out}}\), so the weighted sums and backward gradients start at a useful scale.
- Layer normalization: center and rescale the features during training, so the next layer receives inputs at a controlled scale.
- Residual connections: add \(\mathbf h^{(l-1)}\) to the layer’s output. This adds \(\mathbf I\) to its Jacobian and gives information and gradients a direct path through the layer.
Initialization
We choose initial weights before seeing the gradients that training will produce. We would like a layer to preserve, on average, the size of its inputs and of the gradients passed backward. We measure size by expected squared length, summing the squared coordinates before averaging over the random initialization. This gives a scale to control through the weight distribution. It does not require every realized Jacobian to preserve every vector’s length.
Focus on one layer and leave off the layer index on \(\mathbf W\) and \(\mathbf z\). Draw independent, mean-zero weights with variance \(s^2\). First take \(g(z)=z\), so \(\mathbf h^{(l)}=\mathbf z\) and we can isolate the effect of the weights. We will return to the activation afterward.
Forward: how large is \(\mathbf z\)? Assume the input is independent of this layer’s random weights. Expand the squared length of \(\mathbf z=\mathbf W\mathbf h^{(l-1)}\). The cross terms have expectation zero because distinct weights are independent and mean zero: \[ \begin{aligned} \mathbb E\|\mathbf z\|_2^2 &=\sum_{i=1}^{n_{\mathrm{out}}}\sum_{j=1}^{n_{\mathrm{in}}} s^2\,\mathbb E\bigl[(h_j^{(l-1)})^2\bigr]\\ &=n_{\mathrm{out}}s^2\,\mathbb E\|\mathbf h^{(l-1)}\|_2^2. \end{aligned} \] There are \(n_{\mathrm{out}}\) output coordinates, each receiving contributions with weight variance \(s^2\). The forward squared-length multiplier is therefore \(n_{\mathrm{out}}s^2\). Choosing \(s^2=1/n_{\mathrm{out}}\) makes it one.
Backward: how large is \(\nabla_{\mathbf h^{(l-1)}}\ell\)? The chain rule gives \(\nabla_{\mathbf h^{(l-1)}}\ell=\mathbf W^\top\nabla_{\mathbf h^{(l)}}\ell\) for this linear layer. To estimate its size, treat the incoming gradient as independent of \(\mathbf W\). This is an approximation in a network, since the incoming gradient depends on the weights. The same expansion, now with \(\mathbf W^\top\), gives \[ \begin{aligned} \mathbb E\|\nabla_{\mathbf h^{(l-1)}}\ell\|_2^2 &=\sum_{j=1}^{n_{\mathrm{in}}}\sum_{i=1}^{n_{\mathrm{out}}} s^2\,\mathbb E\!\left[\left(\frac{\partial\ell}{\partial h_i^{(l)}}\right)^2\right]\\ &=n_{\mathrm{in}}s^2\,\mathbb E\|\nabla_{\mathbf h^{(l)}}\ell\|_2^2. \end{aligned} \] The backward squared-length multiplier is \(n_{\mathrm{in}}s^2\). Choosing \(s^2=1/n_{\mathrm{in}}\) makes it one.
When the widths match, \(n_{\mathrm{in}}=n_{\mathrm{out}}=n\), both calculations give the same answer: weight variance \(1/n\). Without this scaling, variance-one weights would multiply expected squared lengths by \(n\) at each layer. With it, both expected squared lengths are preserved through the linear layer. This controls the average scale at initialization. Particular gradient directions can shrink or grow under the realized weights.
When the widths differ, one variance cannot make both multipliers one. One compromise is to make their average equal to one: \((n_{\mathrm{in}}s^2+n_{\mathrm{out}}s^2)/2=1\). Solving for \(s^2\) gives Xavier initialization: \[ \operatorname{Var}(W_{ij})=\frac{2}{n_{\mathrm{in}}+n_{\mathrm{out}}}. \] The two squared-length multipliers then average to one. For example, draw each weight from a mean-zero normal distribution with this variance.
The calculation so far used an identity activation to isolate the weighted sum. It also approximates activations that behave roughly like the identity near zero. ReLU changes the scale because it sets negative coordinates to zero. For any scalar \(z\), \[ \operatorname{ReLU}(z)^2+\operatorname{ReLU}(-z)^2=z^2. \] If the preactivation distribution is symmetric about zero, the two terms on the left have equal expectations. Thus \(\mathbb E[\operatorname{ReLU}(z)^2]=\tfrac12\mathbb E[z^2]\). For equal-width layers, the forward squared-length multiplier becomes \(ns^2/2\). Setting it to one gives He initialization, with weight variance \(2/n\). The backward calculation must include the ReLU derivative, which is one on positive preactivations and zero on negative ones. For the backward scale estimate, also approximate these gates as independent of the weights and the incoming gradient. Under a symmetric continuous preactivation model, each gate is one with probability \(1/2\), giving the same multiplier \(ns^2/2\) under this approximation. See Glorot and Bengio’s paper for the Xavier argument.
Layer Normalization
Initialization chooses the weight scale once, but training changes the weights. We can also control the feature scale each time we evaluate a layer. Layer normalization centers and rescales the coordinates of one example’s feature vector.
Here we apply it after the activation: \[ \mathbf h^{(l)}=\operatorname{LN}\!\left(g(\mathbf z^{(l)})\right). \] This keeps the features passed to the next layer at a controlled scale. Normalization can also appear before an activation or at the entrance to a residual branch, as we will see in Transformers. Its position is part of the network design.
To define the operation, let \(\mathbf a=g(\mathbf z^{(l)})\in\mathbb R^{n_{\mathrm{out}}}\) be the vector we are normalizing. Compute its coordinate mean and variance, then center and rescale: \[ \mu=\frac1{n_{\mathrm{out}}}\sum_{j=1}^{n_{\mathrm{out}}}a_j,\qquad \sigma^2=\frac1{n_{\mathrm{out}}}\sum_{j=1}^{n_{\mathrm{out}}}(a_j-\mu)^2,\qquad \widehat a_j=\frac{a_j-\mu}{\sqrt{\sigma^2+\varepsilon}}. \] The small \(\varepsilon>0\) prevents division by zero. The normalized coordinates have mean zero and variance close to one when \(\sigma^2\) is large compared with \(\varepsilon\).
Layer normalization subtracts the feature mean and divides by the square root of feature variance plus a small positive stabilizer.
Centering sets the coordinate mean to zero, and rescaling fixes the scale up to the effect of \(\varepsilon\). To let training adjust the resulting representation, the network learns a scale and offset for each coordinate: \[ h_j^{(l)}=\gamma_j\widehat a_j+\beta_j. \] Typically \(\gamma_j\) starts at one and \(\beta_j\) at zero. Training can change them if another scale is useful. Normalization controls the features before this learned adjustment. Its own Jacobian can shrink, amplify, or remove gradient directions. Problem 13 explores which directions it removes.
Layer normalization uses the features of one example. Batch normalization instead computes each feature’s statistics across examples in a batch. The layer normalization paper develops the operation we use here.
Residual Connections
Backpropagation multiplies by the full layer Jacobian, including the activation and any normalization. These operations can suppress a gradient direction even when the feature vector has a controlled length. A direct copy of the input gives both the features and their gradients a route through the layer whose derivative is the identity. A residual connection passes that input directly to the next layer and adds the learned transformation to it. For matching input and output widths, \[ \mathbf h^{(l)} =g(\mathbf W^{(l)}\mathbf h^{(l-1)}) {\color{#44AA99}{+\,\mathbf h^{(l-1)}}}. \] The layer can learn a correction without having to reconstruct the entire input. When the learned branch outputs zero, the input passes through unchanged.

Differentiating gives the same layer Jacobian as before, plus an identity: \[ \mathbf J^{(l)} =\frac{\partial\mathbf h^{(l)}}{\partial\mathbf h^{(l-1)}} =\operatorname{diag}\!\left(g'(\mathbf z^{(l)})\right)\mathbf W^{(l)} {\color{#44AA99}{+\,\mathbf I}}. \] In the backward pass, the identity contribution passes the incoming loss gradient directly to the previous layer. The identity path preserves every direction and length. In the full Jacobian, the learned branch can amplify or cancel that contribution. When the branch’s derivative is small, the full Jacobian stays close to the identity.
The branch can contain several operations rather than just one weighted sum and activation. Its Jacobian still gains an identity contribution from the shortcut.
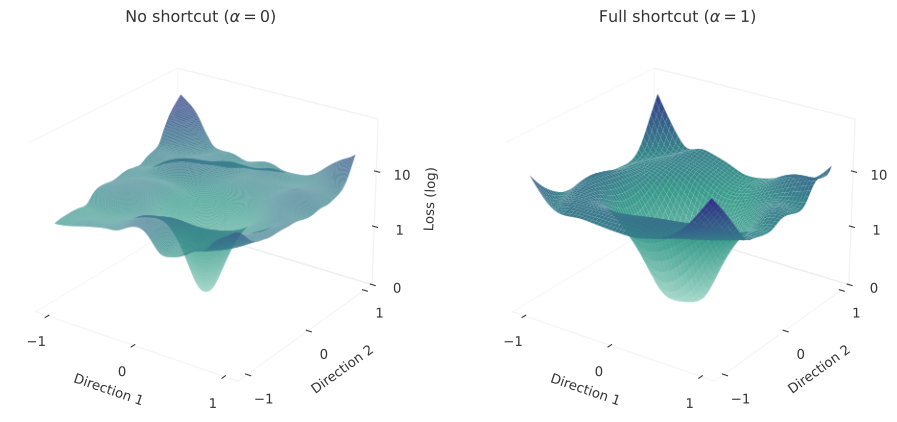
We can visualize the effect of residual connections on training loss using ResNet-56, a 56-layer image classifier, trained on CIFAR-10, which contains small color images in ten classes. The figure compares five separately trained models with shortcut strengths \(\alpha\) from zero (removed) to one (full strength), using the same initial weights and training procedure.