Low-Rank Approximation
A matrix may contain millions of entries even when most of its variation can be described using just a few directions. The singular value decomposition (SVD) identifies those directions and tells us exactly what we lose by discarding the others.
We will prove that truncating the SVD gives the best low-rank approximation and use that result to compress matrices.
Singular Directions
Let \(\mathbf A\in\mathbb R^{m\times n}\) have rank \(r\). Its singular value decomposition can be written as a sum of outer products:
\[ \mathbf A=\sum_{i=1}^r\sigma_i\mathbf u_i\mathbf v_i^\top, \qquad \sigma_1\geq\sigma_2\geq\cdots\geq\sigma_r>0\quad\text{when }r>0. \]
For \(i=1,\ldots,r\), the left singular vectors \(\mathbf u_i\in\mathbb R^m\) are orthonormal, as are the right singular vectors \(\mathbf v_i\in\mathbb R^n\). Each outer product has rank one. In particular,
\[ \mathbf A\mathbf v_i=\sigma_i\mathbf u_i. \]
The matrix takes the input direction \(\mathbf v_i\), scales it by \(\sigma_i\), and sends it to the output direction \(\mathbf u_i\). Larger singular values correspond to stronger actions.
For an integer \(k\) with \(0\leq k\leq r\), the rank-\(k\) truncated SVD keeps only the first \(k\) terms:
\[ \mathbf A_k=\sum_{i=1}^k\sigma_i\mathbf u_i\mathbf v_i^\top. \]
A sum over an empty index range is zero, so \(\mathbf A_0=\mathbf0\). We take \(\mathbf A_k=\mathbf A\) for \(k\geq r\). For \(0\leq k\leq r\), \(\mathbf A_k\) is a sum of \(k\) rank-one matrices, so its rank is at most \(k\).
Measuring Error with the Frobenius Norm
For \(\mathbf M\in\mathbb R^{m\times n}\), the Frobenius norm treats all entries as one long vector. Summing over its \(m\) rows and \(n\) columns gives
\[ \|\mathbf M\|_F^2=\sum_{i=1}^m\sum_{j=1}^n M_{ij}^2. \]
Two elementary trace identities make this norm especially convenient. The trace of a square matrix is the sum of its diagonal entries. Let \(\mathbf X\in\mathbb R^{p\times q}\) and \(\mathbf Y\in\mathbb R^{q\times p}\), so \(\mathbf X\mathbf Y\) is \(p\times p\) and \(\mathbf Y\mathbf X\) is \(q\times q\). Expanding the diagonal entries and reversing the order of the finite sums gives
\[ \begin{aligned} \operatorname{tr}(\mathbf X\mathbf Y) &=\sum_{i=1}^p\sum_{j=1}^q X_{ij}Y_{ji}\\ &=\sum_{j=1}^q\sum_{i=1}^p Y_{ji}X_{ij}\\ &=\operatorname{tr}(\mathbf Y\mathbf X). \end{aligned} \]
Likewise, \(\mathbf M^\top\mathbf M\) is \(n\times n\). Its \(j\)th diagonal entry is the squared length of column \(j\) of \(\mathbf M\), so
\[ \operatorname{tr}(\mathbf M^\top\mathbf M) =\sum_{j=1}^n\sum_{i=1}^m M_{ij}^2 =\|\mathbf M\|_F^2. \]
Applying these identities to the SVD, both indices range over the \(r\) singular directions. Orthonormality gives \(\mathbf u_i^\top\mathbf u_j=0\) when \(i\ne j\) and \(1\) when \(i=j\), so only terms with matching indices remain:
\[ \begin{aligned} \mathbf A^\top\mathbf A &=\sum_{i=1}^r\sum_{j=1}^r \sigma_i\sigma_j\mathbf v_i(\mathbf u_i^\top\mathbf u_j)\mathbf v_j^\top\\ &=\sum_{i=1}^r\sigma_i^2\mathbf v_i\mathbf v_i^\top. \end{aligned} \]
Taking the trace, and using \(\mathbf v_i^\top\mathbf v_i=1\), gives
\[ \|\mathbf A\|_F^2=\sum_{i=1}^r\sigma_i^2. \]
The residual \(\mathbf A-\mathbf A_k\) consists of the discarded outer products, so the same calculation gives
\[ \|\mathbf A-\mathbf A_k\|_F^2=\sum_{i=k+1}^r\sigma_i^2. \]
The squared singular values are sometimes called the matrix’s energy. For \(k<r\), keeping one more direction reduces the squared error by exactly \(\sigma_{k+1}^2\). If the spectrum drops sharply, a small rank may capture almost all the energy; if it decays slowly, the residual will remain substantial.
Why Truncation Is Optimal
So far we know the total squared error of the truncated SVD. To prove optimality, we will first bound the largest error on a unit input, then use that bound to control every singular value of the error matrix. The spectral norm measures this largest error:
\[ \|\mathbf M\|_2=\max_{\|\mathbf x\|_2=1}\|\mathbf M\mathbf x\|_2. \]
As the decompositions reading showed, this is the largest singular value of \(\mathbf M\). The residual \(\mathbf A-\mathbf A_k\) has singular values \(\sigma_{k+1},\ldots,\sigma_r\), so its spectral norm is \(\sigma_{k+1}\) when \(k<r\).
Claim: (Eckart–Young–Mirsky theorem.) For \(0\leq k<r\), the truncated SVD minimizes both errors:
\[ \min_{\operatorname{rank}(\mathbf B)\leq k} \|\mathbf A-\mathbf B\|_2 =\|\mathbf A-\mathbf A_k\|_2 =\sigma_{k+1}, \]
\[ \min_{\operatorname{rank}(\mathbf B)\leq k} \|\mathbf A-\mathbf B\|_F^2 =\|\mathbf A-\mathbf A_k\|_F^2 =\sum_{i=k+1}^r\sigma_i^2. \]
For \(k\geq r\), both minima are zero.
Proof
Take any \(\mathbf B\in\mathbb R^{m\times n}\) with rank at most \(k<r\). We will find a unit input on which \(\mathbf B\) vanishes but \(\mathbf A\) produces an output of length at least \(\sigma_{k+1}\).
The null space \(\mathcal N(\mathbf B)=\{\mathbf x\in\mathbb R^n:\mathbf B\mathbf x=\mathbf0\}\) has dimension at least \(n-k\) by the rank–nullity theorem. Let \(S=\operatorname{span}\{\mathbf v_1,\ldots,\mathbf v_{k+1}\}\). Because these singular vectors are orthonormal, \(\dim S=k+1\), and
\[ \dim\mathcal N(\mathbf B)+\dim S\geq(n-k)+(k+1)=n+1. \]
Two subspaces of \(\mathbb R^n\) whose dimensions sum to more than \(n\) must share a nonzero vector. Choose a unit vector \(\mathbf x\) in their intersection and write \(\mathbf x=\sum_{i=1}^{k+1}c_i\mathbf v_i\), where \(c_i=\mathbf v_i^\top\mathbf x\) and \(\sum_{i=1}^{k+1}c_i^2=1\). Then \(\mathbf B\mathbf x=\mathbf0\), and orthonormality of the left singular vectors gives
\[ \begin{aligned} \|\mathbf A-\mathbf B\|_2^2 &\geq\|(\mathbf A-\mathbf B)\mathbf x\|_2^2 =\|\mathbf A\mathbf x\|_2^2\\ &=\sum_{i=1}^{k+1}\sigma_i^2c_i^2 \geq\sigma_{k+1}^2\sum_{i=1}^{k+1}c_i^2 =\sigma_{k+1}^2. \end{aligned} \]
The truncated SVD attains this bound, proving the spectral-norm result.
For the Frobenius norm, let \(\mathbf E=\mathbf A-\mathbf B\) and write its singular values as \(\tau_1\geq\cdots\geq\tau_p\geq0\), where \(p=\min(m,n)\) and zeros are included. We will use the spectral result to bound each \(\tau_j\) for \(j=1,\ldots,r-k\). Let \(\mathbf E_{j-1}\) be the truncated SVD retaining the first \(j-1\) singular components of \(\mathbf E\), with \(\mathbf E_0=\mathbf0\). Adding these components to \(\mathbf B\) produces an approximation of rank at most \(k+j-1\): its columns lie in the sum of the two column spaces. The spectral result, applied with this larger rank limit, gives
\[ \begin{aligned} \sigma_{k+j} &\leq\|\mathbf A-(\mathbf B+\mathbf E_{j-1})\|_2\\ &=\|\mathbf E-\mathbf E_{j-1}\|_2 =\tau_j. \end{aligned} \]
Summing the squared bounds gives
\[ \begin{aligned} \|\mathbf A-\mathbf B\|_F^2 &=\sum_{j=1}^p\tau_j^2 \geq\sum_{j=1}^{r-k}\sigma_{k+j}^2\\ &=\sum_{i=k+1}^r\sigma_i^2 =\|\mathbf A-\mathbf A_k\|_F^2. \end{aligned} \]
This proves the Frobenius result as well. For \(k\geq r\), choosing \(\mathbf B=\mathbf A\) gives zero error in both norms.
A rank-\(k\) approximation must miss a direction among the first \(k+1\) singular vectors. Applying that same restriction after adding components of the residual accounts for every discarded singular value of \(\mathbf A\). Thus truncation minimizes both worst-case error and total squared error. If \(1\leq k<r\) and \(\sigma_k=\sigma_{k+1}\), different rank-\(k\) matrices may attain the same optimal error.
Compression
An image gives us a visible example of low-rank approximation. Each color channel is a matrix of pixel intensities, so truncating its SVD lets us watch detail return as we keep more singular directions.
An \(m\times n\) dense matrix needs \(mn\) numbers to store. The approximation
\[ \mathbf A_k=\mathbf U_k\boldsymbol\Sigma_k\mathbf V_k^\top \]
can instead be stored using \(mk\) entries of \(\mathbf U_k\), \(k\) singular values, and \(nk\) entries of \(\mathbf V_k\): a total of \(k(m+n+1)\) numbers. This is a saving when \(k(m+n+1)\) is much smaller than \(mn\).
The reconstructions below use the same rank limit in all three color channels.
Processing image…
|
|
|
|
|
|
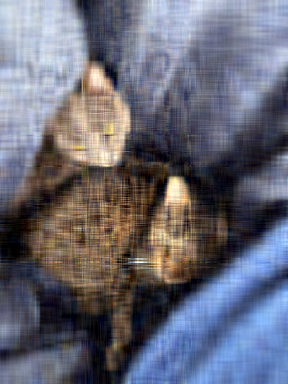
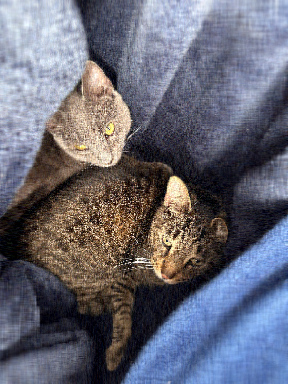
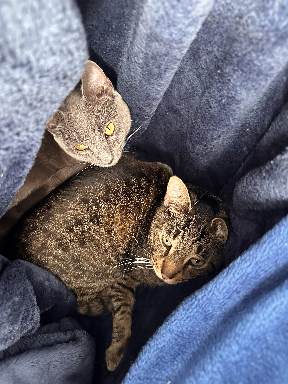
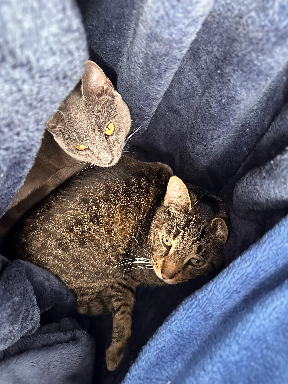
For Ivy and Stripes, low ranks keep broad patches of color, while higher ranks recover details in the fur and blanket.
Storing the factors also speeds up matrix-vector multiplication. We can compute
\[ \mathbf A_k\mathbf x =\mathbf U_k\bigl(\boldsymbol\Sigma_k(\mathbf V_k^\top\mathbf x)\bigr) \]
using the thin factors, at a cost proportional to \(k(m+n)\) instead of \(mn\) arithmetic operations.
Eckart–Young–Mirsky gives the smallest possible error among matrices of the chosen rank. The factor count measures how many numbers the representation stores; an image file format also chooses how to encode those numbers.
Adapting a Model with LoRA
A pretrained neural network already contains useful features, but adapting it to a new task can require updating and storing millions of weights. Low-rank adaptation (LoRA) keeps a weight matrix \(\mathbf W\in\mathbb R^{m\times n}\) fixed and learns a compact change [HS+, ’21]. Choose an integer \(1\leq k\leq\min(m,n)\) and write \[ \mathbf W_{\mathrm{new}}=\mathbf W+\mathbf B\mathbf C, \qquad \mathbf B\in\mathbb R^{m\times k},\quad \mathbf C\in\mathbb R^{k\times n}. \] Every column of \(\mathbf B\mathbf C\) lies in the span of the \(k\) columns of \(\mathbf B\), so the change has rank at most \(k\). Conversely, the SVD factors any change of rank at most \(k\) into matrices of these shapes, padding with zeros when needed. Thus the rank budget limits how many independent directions the model can change.
Training the two factors uses \(k(m+n)\) parameters, compared with \(mn\) for a dense update. This saves trainable parameters when \(k(m+n)<mn\). For an input \(\mathbf x\in\mathbb R^n\), the adapted layer computes \(\mathbf W\mathbf x+\mathbf B(\mathbf C\mathbf x)\). After training, we can merge the product into \(\mathbf W\) and use a single matrix multiplication. LoRA learns the factors from task data; its usefulness depends on whether a small number of update directions suffices for that task.
Reconstructing Model Benchmark Scores
Language models are tested on many benchmarks: answering factual questions, solving math problems, writing code, and so on. If a model does well on one test, it often does well on others. Can a few singular directions capture those shared patterns?
The table below comes from the Observational Scaling Laws study. Each row is a language model, and each column is a benchmark. We use the 124 models with complete scores on eight benchmarks and subtract each column’s mean to obtain a matrix \(\mathbf A\in\mathbb R^{124\times8}\).
Keep just the first three terms of its SVD to form \(\mathbf A_3\). By Eckart–Young–Mirsky, this is the rank-three approximation with the smallest squared reconstruction error:
\[ \|\mathbf A-\mathbf A_3\|_F^2 =\sum_{i=4}^{8}\sigma_i^2. \]
For this table, the first three singular directions retain 97.4% of the squared variation:
\[ \frac{\sigma_1^2+\sigma_2^2+\sigma_3^2} {\sum_{i=1}^{8}\sigma_i^2} \approx 0.974. \]
We add the column means back to compare the reconstructed scores with the measurements. The figure shows a few rows and columns; the ellipses stand for the rest.

So eight scores per model can be approximated by three coordinates per model and a shared set of singular directions. These are reconstructions of the scores we used to fit the approximation; we have not predicted results on unseen models or benchmarks. The data and calculation document the fit, using the study’s released benchmark table.
Problem 15 asks how much of an exactly rank-\(k\) matrix we need to measure to recover it. The embeddings reading will explain how to compute a few coordinates for each example from the singular directions. Applied to centered data, this is principal component analysis (PCA).