Positional Embeddings
Content-only self-attention assigns the same key and value to identical input vectors wherever they appear. Reordering the input vectors reorders the outputs. We will add position information and study how rotary embeddings make attention scores depend on the distance between tokens.
Position Information
The self-attention reading established that content-only attention is permutation-equivariant: \[ \operatorname{Attention}(\mathbf P\mathbf X) =\mathbf P\operatorname{Attention}(\mathbf X). \] The strings “dog bites man” and “man bites dog” contain the same content embeddings, so position must supply which noun came first.
Repeated tokens also receive equal content scores, so a query cannot prefer the more recent occurrence without position.
Position can enter in two broad forms. An absolute scheme assigns a vector \(\mathbf p_m\) to position \(m\) and adds it to the token representation, \[ \mathbf x_m\leftarrow\mathbf x_m+\mathbf p_m. \] The vectors may be learned or generated by a fixed formula. A learned table has no entry beyond its stored range, while a fixed formula can be evaluated there without guaranteeing that the trained model will use the new positions correctly.
A relative scheme describes the offset \(n-m\) between a query position \(m\) and key position \(n\). Relative structure matches many reusable rules: “the preceding token,” “the note two beats earlier,” or “the event shortly before this one” can occur anywhere. The design goal is therefore an attention score that depends on positions through \(n-m\), while content still determines what is being compared.
Absolute and relative information can coexist. Rotary positional embeddings (RoPE) [SLPMWL, ’21] make relative displacement appear directly inside query-key scores.
Rotary Embeddings
RoPE applies position after the learned query and key projections and before their dot product. Begin in two dimensions, \(d_k=2\). For angular frequency \(\theta\), define the rotation associated with position \(m\): \[ \mathbf R_m= \begin{bmatrix} \cos(m\theta)&-\sin(m\theta)\\ \sin(m\theta)&\cos(m\theta) \end{bmatrix}. \] The query at \(m\) becomes \(\mathbf R_m\mathbf q\), the key at \(n\) becomes \(\mathbf R_n\mathbf k\), and values are unchanged.
Rotation is chosen because the attention score already compares a query and key through an inner product. Applying one transform to each vector makes their relative transform appear automatically as \((\mathbf R_m)^{\top}\mathbf R_n\). The next result checks that this product removes the common absolute location while preserving the score scale.
Claim: The rotated query–key score depends on position only through the offset \(n-m\), \[ s_{mn}=\frac{\mathbf q^\top\mathbf R_{n-m}\mathbf k}{\sqrt{d_k}}. \] The rotation also preserves the norms of queries and keys.
Proof
Write \(\mathbf R(\phi)\) for a rotation by angle \(\phi\), so \(\mathbf R_m=\mathbf R(m\theta)\). Transposition changes the sign of the off-diagonal sine entries, giving \(\mathbf R(\phi)^\top=\mathbf R(-\phi)\). Direct matrix multiplication and the angle-difference identities give \[ \begin{aligned} (\mathbf R_m)^{\top}\mathbf R_n &=\mathbf R(-m\theta)\mathbf R(n\theta)\\ &= \begin{bmatrix} \cos((n-m)\theta)&-\sin((n-m)\theta)\\ \sin((n-m)\theta)&\cos((n-m)\theta) \end{bmatrix}\\ &=\mathbf R_{n-m}. \end{aligned} \] Therefore the scaled dot product is \[ \begin{aligned} s_{mn} &=\frac{(\mathbf R_m\mathbf q)^\top (\mathbf R_n\mathbf k)}{\sqrt{d_k}}\\ &=\frac{\mathbf q^\top(\mathbf R_m)^{\top} \mathbf R_n\mathbf k}{\sqrt{d_k}}\\ &=\frac{\mathbf q^\top\mathbf R_{n-m}\mathbf k}{\sqrt{d_k}}. \end{aligned} \] Setting \(n=m\) in the rotation product gives \((\mathbf R_m)^{\top}\mathbf R_m=\mathbf I\), so \[ \|\mathbf R_m\mathbf q\|_2^2 =\mathbf q^\top(\mathbf R_m)^{\top}\mathbf R_m\mathbf q =\|\mathbf q\|_2^2. \] The same orthogonality identity at position \(n\) gives \(\|\mathbf R_n\mathbf k\|_2^2=\|\mathbf k\|_2^2\). Taking nonnegative square roots proves norm preservation for both vectors.
Shifting both positions by the same amount leaves their positional contribution to the score unchanged.
Rotating a query by mθ and a key by nθ makes their dot product depend on (n − m)θ. With identical content, equal offsets give equal matrix entries.
The score matrix uses identical content at every position, so its diagonal stripes isolate the positional effect. RoPE changes alignments without making later query or key vectors systematically larger.
The usual construction leaves values unchanged: position changes the attention scores, while values carry the selected content.
The full transformer need not be translation invariant because content, boundaries, and the causal mask can still change its output after a shift.
If identical content is repeated at every position, the score \(s_{mn}\) is a function of \(n-m\) alone. The resulting score matrix is constant along each diagonal, a structure called Toeplitz. Varying token content overlays content-dependent variation on this positional pattern.
Rotation Frequencies
One planar rotation repeats after a full turn, so it cannot distinguish every offset. A real attention head therefore splits its even-dimensional query and key vectors into two-dimensional pairs and rotates each pair at a different frequency. With base \(B>1\), a common ladder is \[ \theta_j=B^{-2j/d_k}, \qquad j=0,\ldots,d_k/2-1. \] The full rotation matrix \(\boldsymbol\Theta_m\) is block diagonal, one \(2\times2\) block per frequency.
Products and transposes of block-diagonal matrices act separately on each block. Applying the planar identity to every coordinate pair therefore gives \[ (\boldsymbol\Theta_m)^\top\boldsymbol\Theta_n =\boldsymbol\Theta_{n-m}. \] Setting \(n=m\) gives the identity matrix, so the full rotation also preserves norms. The higher-dimensional construction reuses the same proof at several frequencies.
The frequencies themselves form a geometric ladder. On a logarithmic vertical scale, equal steps through the coordinate pairs produce equal downward steps in frequency, making the range from fast local changes to slow long-range changes visible at once.
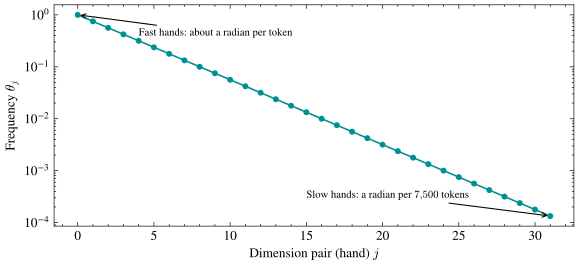
Fast rotations change sharply across nearby offsets, while slow rotations vary across longer distances.
The learned query and key projections decide how much content lands in each pair. A head can rely more on fast or slow changes as training demands. The frequency ladder supplies positional behaviors that each head can combine differently.
Because each rotation is periodic, two offsets can look similar at one frequency. Using several frequencies gives the model additional scales on which to distinguish them.
The causal mask and RoPE have separate roles. The mask distinguishes past from future by visibility, while RoPE describes displacement among visible positions.
Extending context changes which phases the model encounters, and compressing positions changes the phase differences it learned for nearby tokens. Formulas can describe those distortions but cannot reveal which frequencies a trained head relies on, so context extension still requires empirical validation.
RoPE applies an absolute rotation to each query and key, but their dot product depends on the difference between those rotations. Using multiple frequencies represents displacement at several scales while preserving query and key norms.