Reinforcement Learning
Consider a cart that must move left or right to keep a pole balanced. A movement changes both the immediate outcome and the situation the controller will face next. We will describe this interaction with a policy and a trajectory, then combine rewards across time to define what the policy should optimize.
States and Actions
At each integer time \(t\geq0\), an agent observes a state \(s_t\in\mathcal S\), chooses an action \(a_t\in\mathcal A\), and receives a scalar reward \(r_t\) and next state \(s_{t+1}\) from the environment. The sets \(\mathcal S\) and \(\mathcal A\) contain the possible states and actions.
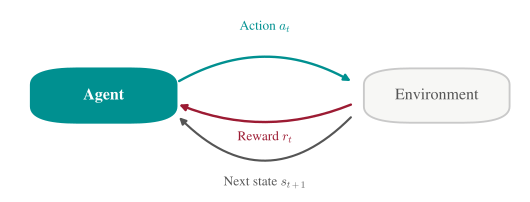
For the cart, the state can include position, velocity, pole angle, and angular velocity. The action chooses a push direction. A reward can count time spent balanced. The reward evaluates the outcome of the chosen action. The agent must learn which choices lead to higher rewards. Assigning delayed outcomes to earlier decisions is the credit-assignment problem.
This loop is formalized as a Markov decision process. Besides the state and action spaces, it has a transition distribution \(P(s_{t+1}\mid s_t,a_t)\) and a reward produced by the transition. The Markov property says that the current state contains the past information needed to predict what happens next: once \(s_t\) and \(a_t\) are known, earlier history adds nothing to the transition distribution. The property states what the word “state” must contain for this model.
An episode is one run from an initial state until termination. Unlike a fixed dataset, the collection of episodes depends on the agent’s behavior. If it never tries an action, it gathers no direct evidence about that action’s consequences.
If an observation omits information needed to predict the future, such as velocity when only position is visible, it is not a Markov state. The analysis below assumes the state is sufficient.
Policies and Trajectories
The agent’s decision rule is a policy \(\pi\). For each state, it gives a distribution over actions, \[ a_t\sim\pi(\cdot\mid s_t). \] A deterministic policy puts all probability on one action. A stochastic policy deliberately retains randomness, which both supports exploration and later makes the expected reward differentiable through the policy’s probabilities.
Running a policy in an environment produces a trajectory \[ \tau=(s_0,a_0,r_0,s_1,a_1,r_1,\ldots). \] The trajectory is one sampled outcome, but its components are dependent because each action affects later states and decisions.
Both the policy and the environment may be random. Thus even a fixed policy induces a distribution over trajectories. We optimize expected performance under that distribution. If \(G_0\) denotes the total return from the start, \[ J(\pi)=\mathbb E_{\tau\sim\pi}[G_0]. \] Episodes let us estimate this expectation by Monte Carlo averaging. The next reading will differentiate it without differentiating through the environment.
Discounted Return
To connect future rewards with the decision at time \(t\), define the discounted return \[ G_t=r_t+\gamma r_{t+1}+\gamma^2r_{t+2}+\cdots =\sum_{k=0}^{\infty}\gamma^kr_{t+k}, \qquad 0\leq\gamma<1. \]
Discounting gives later rewards a path back to the current decision and limits how much a long future can contribute. The zero-delay weight \(\gamma^0\) is one, including when \(\gamma=0\).
Claim: If a finite constant \(R_{\max}\geq0\) bounds every reward as \(|r_t|\leq R_{\max}\) for all \(t\geq0\), and \(0\leq\gamma<1\), the discounted return is finite and obeys \[ G_t=r_t+\gamma G_{t+1}. \] The discount weights have total mass \(1/(1-\gamma)\), which defines their rough effective horizon, and for every integer \(H\geq0\) the fraction of that mass assigned at least \(H\) steps ahead is \(\gamma^H\).
Proof
For an integer \(H\geq1\), define the finite geometric sum \(S_H=\sum_{k=0}^{H-1}\gamma^k\). Multiplication and subtraction give \[ (1-\gamma)S_H =(1+\gamma+\cdots+\gamma^{H-1}) -(\gamma+\gamma^2+\cdots+\gamma^H) =1-\gamma^H. \] At \(H=0\), the same identity holds with \(S_0=0\), using the convention that a sum over an empty index range is zero. Because \(0\leq\gamma<1\), \(\gamma^H\to0\), so \(\sum_{k=0}^{\infty}\gamma^k=1/(1-\gamma)\). Bounded rewards then give \[ \sum_{k=0}^{\infty}|\gamma^kr_{t+k}| \leq R_{\max}\sum_{k=0}^{\infty}\gamma^k =\frac{R_{\max}}{1-\gamma}, \] which proves absolute convergence and finiteness of \(G_t\).
Now split the convergent series after its first term: \[ \begin{aligned} G_t &=r_t+\sum_{k=1}^{\infty}\gamma^kr_{t+k}\\ &=r_t+\gamma\sum_{j=0}^{\infty}\gamma^jr_{t+1+j}\\ &=r_t+\gamma G_{t+1}, \end{aligned} \] where \(j=k-1\). Finally, normalize the weights to \(w_k=(1-\gamma)\gamma^k\) for integers \(k\geq0\). Their mass from any integer lag \(H\geq0\) onward is \[ \sum_{k=H}^{\infty}w_k =(1-\gamma)\gamma^H\sum_{j=0}^{\infty}\gamma^j =\gamma^H. \] Thus \(1/(1-\gamma)\) is the total undiscounted-equivalent weight and \(\gamma^H\) gives the exact remaining fraction beyond lag \(H\), proving the effective-horizon statements.
The discount factor \(\gamma\) determines how strongly delay reduces credit. Returns can be computed backward through an observed episode with one multiply and addition per step.
The return at time t sums rewards from that time onward, with successive powers of γ. Splitting off the first reward gives G(t) = r(t) + γ G(t + 1).
Each bar shows how much one observed reward contributes to the selected return. Rewards before the decision do not enter it. The timeline makes the backward recurrence a sum of identifiable contributions.
For a finite episode with \(T\geq1\) decisions, the observed rewards are \(r_0,\ldots,r_{T-1}\). The return at time \(t\in\{0,\ldots,T\}\) is \[ G_t=\sum_{k=0}^{T-t-1}\gamma^k r_{t+k}. \] The empty-sum convention gives \(G_T=0\). Apply \(G_t=r_t+\gamma G_{t+1}\) for \(t=T-1,\ldots,0\). Each reward contributes to the earlier returns, discounted according to its distance from the corresponding decision.
A larger \(\gamma\) gives distant outcomes more influence and includes more distant randomness in the estimate. In a finite episode, the sum remains finite at \(\gamma=1\), so discounting still encodes a modeling choice rather than only a convergence requirement.
Return assigns a later reward to every earlier decision whose \(G_t\) contains it. This makes delayed evidence available without proving that each action caused the reward.
Exploration
At any state, the agent can exploit the action currently believed best or explore an action whose consequences are less certain. Each choice changes which observations the agent collects for training.
Suppose an early accident makes one action look poor. A deterministic policy may stop selecting it and never collect the evidence needed to revise that conclusion. A stochastic policy with positive probability on alternatives continues to generate corrective experience. Too much random action wastes reward. Too little can trap learning inside its current beliefs.
The trajectory distribution changes with the policy, so a poor update can also steer the agent away from useful data.
Evaluation should run the candidate policy because trajectories from an older policy may visit different states.
A policy generates trajectories, discounted return carries later rewards back to earlier decisions, and exploration determines which consequences the agent can observe.